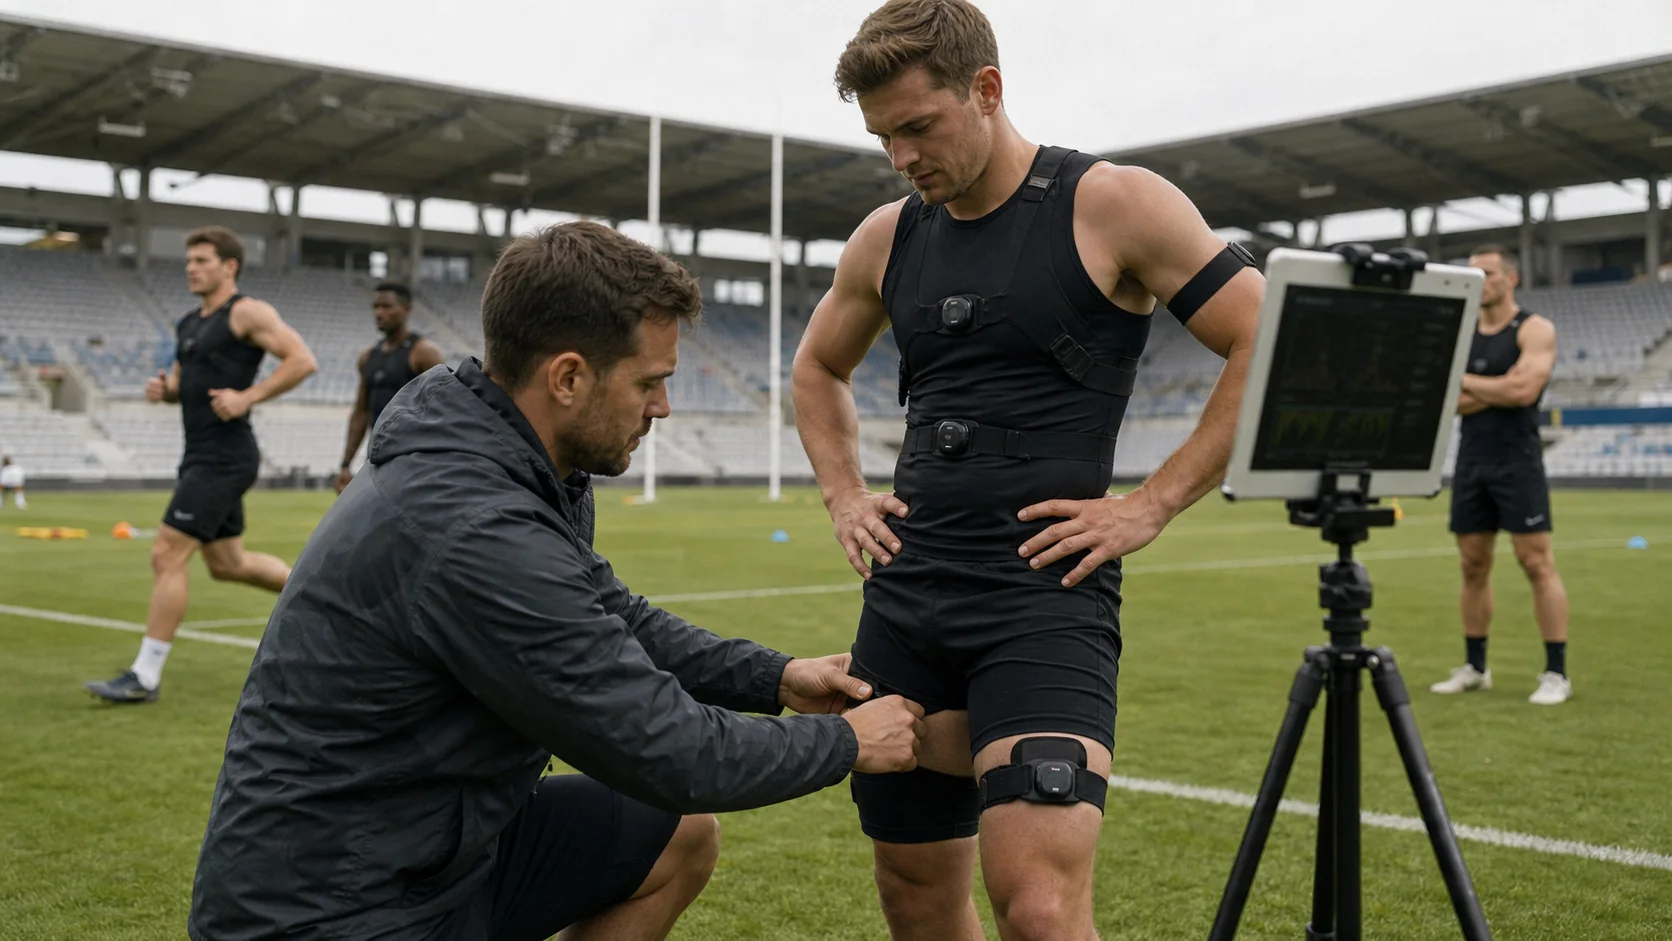
Start with criterion measure, because it shapes the quality of every later comparison. Validation asks whether a device output agrees sufficiently with a reference for a stated use. The useful question is whether agreement is sufficient for the intended claim. A workable operating rule is to state the reference, population, task, and acceptable difference in a protocol. Staff should record the rule in the session plan and apply it consistently across comparable groups. If circumstances force a change, label the change rather than pretending continuity. That discipline protects coaching judgement, reduces avoidable arguments, and makes the resulting history credible enough for careful review.
For this part of the programme, repeatability deserves explicit ownership. Repeatability asks whether the same process produces acceptably similar results when conditions are repeated. Before staff act, they need to establish whether collection is stable from day to day. The best next step is to repeat a subset of trials under realistic staff conditions. This is not bureaucracy for its own sake: it prevents a device output being mistaken for a complete account of performance or readiness. Build the check into the normal handover, then review exceptions with the people closest to the training. A clear limitation is a strength when it prevents an overconfident decision.
A sound implementation treats ecological testing as both a measurement and a people issue. A controlled trial can be clean yet fail to represent the movement, clothing, surface, and fatigue of normal training. That means asking whether a laboratory finding transfers to practice instead of simply accepting the displayed number. Teams can respond by choosing to test representative drills before rollout. Explain the rule to athletes before the relevant session and make the same explanation available to coaches. Where the measure cannot answer the question reliably, say so and use observation or another record. This approach creates a usable boundary around the data and preserves trust when the workflow is under pressure.
The operational test for error tolerance is whether it supports a real decision at the right time. Every decision needs an error tolerance that is smaller than the change staff intend to act upon. Staff must therefore determine whether the signal exceeds expected noise. A practical safeguard is to use smallest-worthwhile-change logic alongside error estimates. Keep the process short enough to survive travel, busy fixtures, and staff absence. Then retain only the context needed to understand the outcome later. The measure should illuminate a decision, not replace the coach, athlete, or welfare lead who carries responsibility for it. That distinction is central to sustainable wearable practice.
Teams often underestimate subgroups until an unusual session exposes the gap. Age, body shape, movement style, and disability can change how a wearable performs across a squad. The decision point is whether validation covers the people being measured. Make the workflow resilient by choosing to include diverse participants and report gaps plainly. Test it during ordinary training rather than first attempting it during a decisive fixture or difficult conversation. If the process fails, preserve the reason for failure alongside the data rather than repairing the record invisibly. That gives the programme an honest evidence trail and a concrete target for the next improvement cycle.
Good wearable practice makes algorithm versions visible before it becomes a disputed conclusion. A software update can alter an output even when the hardware is unchanged. The staff question is whether a new release needs rechecking. To answer it consistently, freeze versions during key comparison periods. Use a named owner for the check and a simple route for athletes to add missing context or raise concern. Avoid escalating a single reading into a judgement about character, commitment, or capability. The goal is a bounded, practical signal that improves planning while respecting uncertainty, individual dignity, and the realities of the sport environment.
selection safeguards is the first practical issue in this workflow. Selection decisions deserve corroboration because measurement error can be mistaken for a difference in ability. The team should decide whether the output can influence a high-stakes outcome before interpretation begins. In practice, require video, coach observation, or a second measure before selection action. This keeps the output connected to an observable training question rather than a generic score. It also gives athletes and staff a way to challenge a record that does not match the session. The result is a repeatable process with limits stated upfront, which is more useful than a polished dashboard detached from practice.