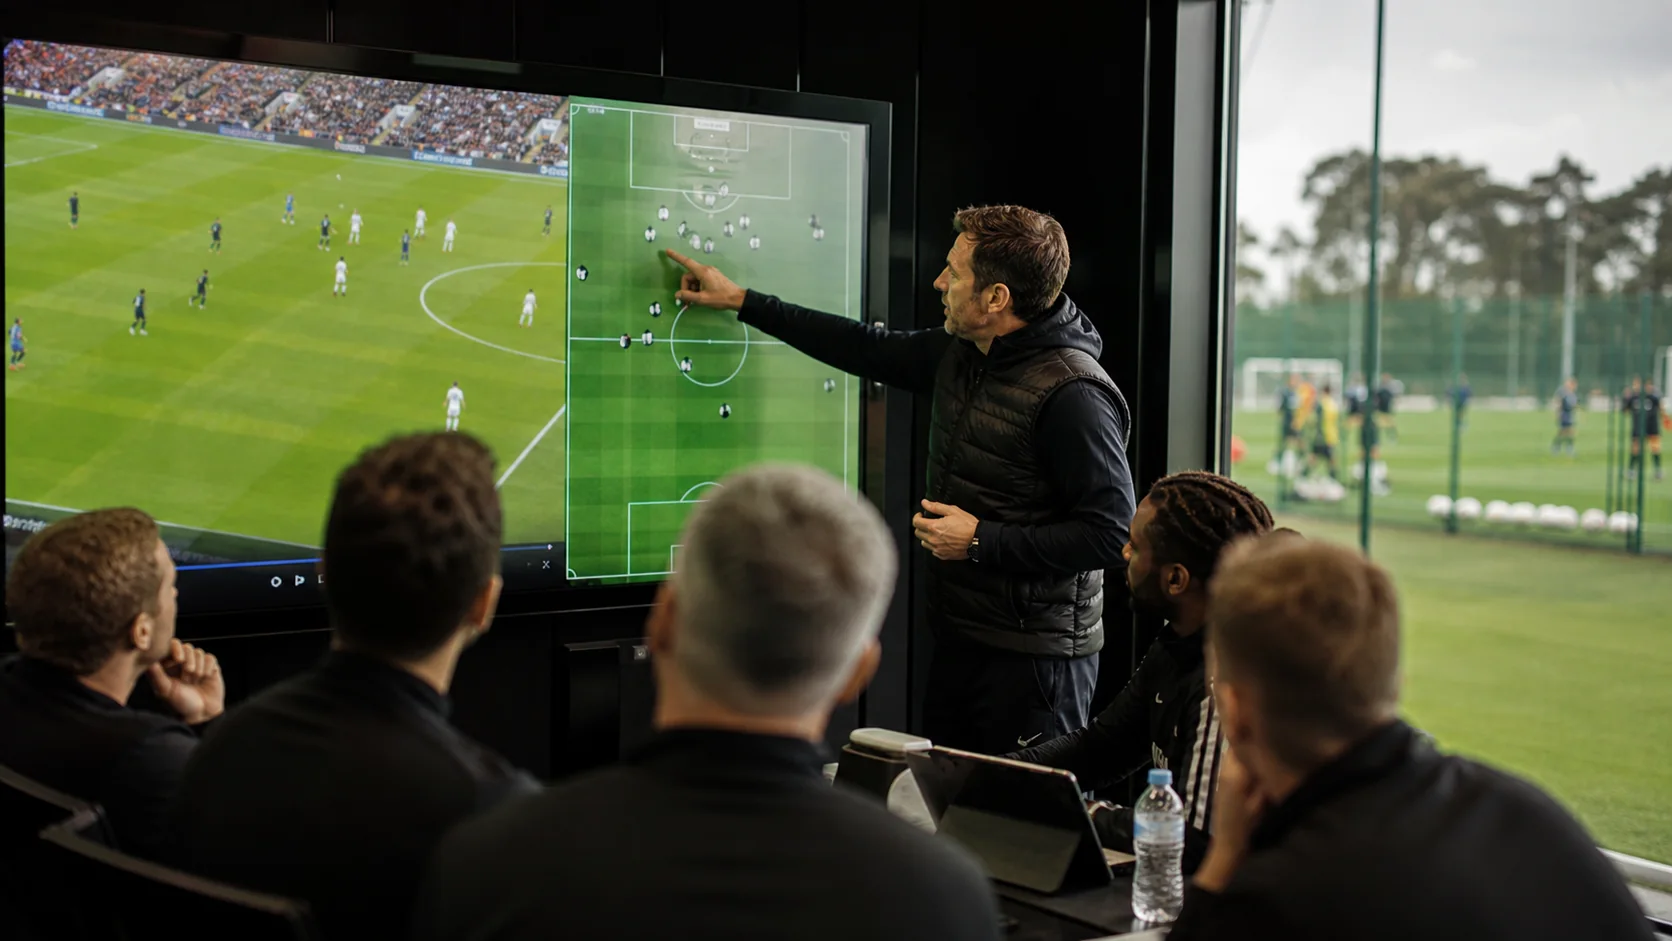
The mechanism rests on the decision statement, representative clips, model or descriptive outputs, input coverage, counterexamples, and an assigned decision owner. The team should document how those signals are created, what can disturb them, and which are merely helpful rather than essential. The working method is to translate analysis into a fixed briefing format that begins with the decision and ends with reversible next actions, while keeping technical detail available on request. That separation matters because a polished output can conceal weak input conditions. Run a controlled test with known reference cases, preserve the raw source material, and compare the derived view against it. Only then can staff understand what the system observes, what it estimates, and what it cannot know.
Explainable decision briefs for coaching staff should be commissioned as a decision system rather than a technical novelty. In a short staff meeting where analysts must support a decision without asking coaches to decode a technical dashboard, the first question is what action is under consideration, what evidence supports each option, and what uncertainty should temper the choice. Establish the intended user, the moment when they act, and the consequence of a wrong answer before selecting tools. This makes the initial scope manageable: identify one review decision, its deadline, and the evidence that must be visible. Give every brief an “I would not conclude” box so the limits are read alongside the headline. The goal is not a richer screen; it is a repeatable way to decide when the information is fit for use.
Measurement should be reported in language connected to the decision. Use whether staff can accurately restate the claim, clip-to-claim traceability, use of counterevidence, and the rate at which a brief produces a recorded follow-up rather than an unexamined preference. Break results down by setting, source condition, and confidence level, rather than publishing one flattering average. Keep a held-out reviewed sample and examine the cases near the action threshold; they often matter more than routine examples. Do not treat a measure as a promise of accuracy outside its tested context. A dashboard that foregrounds coverage and uncertainty is more useful than one that hides them behind a single score.
Implementation should begin with a site and role map, not a procurement checklist. List the physical positions, handoffs, permissions, and failure points that will exist on an ordinary day. Assign one person to approve setup and another to judge analytical fitness, so the same operator is not validating their own work. Use a short readiness checklist, a reversible configuration change, and a documented fallback. This approach exposes tradeoffs early: more coverage may mean more complexity, while simpler capture may leave an important question unanswered. In practice, record this step in the shared operational log so that the next reviewer can see the context, owner, and unresolved question without reconstructing it from memory.
The analyst drafts the brief after checking the source data and selects evidence that includes both supportive and contradictory clips. In the meeting, the analyst states the question before showing any score, records the decision and rationale, and flags what will be observed next. A follow-up review compares the prediction or hypothesis with what happened. The important design choice is that exception handling is part of the routine rather than an embarrassing afterthought. A small, named queue prevents unresolved cases from leaking into summaries. At the end of each cycle, review the reasons items entered that queue and decide whether the issue was capture, definition, process, or model behaviour. That feedback turns daily operations into a controlled improvement loop instead of an untracked collection of fixes.
The practical decision is straightforward: Use an explanation to improve a conversation, not to end it. If a recommendation cannot survive a request for its evidence and exceptions, return to the underlying question. Set a review date and define the evidence needed to expand the scope. A successful pilot leaves behind trained people, usable documentation, and a record of uncertainty—not just a demonstration. That is how an analytics capability can grow while preserving the trust of coaches, officials, athletes, and operations staff. In practice, record this step in the shared operational log so that the next reviewer can see the context, owner, and unresolved question without reconstructing it from memory.
The limits are operational facts: simple explanations can omit interactions, a familiar visual can create false confidence, and no concise brief can turn observational data into proof of causation. Name the decision owner, distinguish advice from authority, and prevent sensitive personal data from appearing in broad meeting materials. Store decision records with access limits and a defined retention period. Build these controls into access design, training, and escalation rather than attaching them after deployment. Staff need permission to say “not reliable enough today” without being treated as obstructive. Periodically invite a user who did not build the process to try to reproduce a result from the documented materials. If they cannot, the process is not yet sufficiently accountable.